


ODM Cloud Series — Crawl / Walk / Run · Article 5 of 10
From zero to a self-hosted cloud processing pipeline
This series builds a production WebODM setup from scratch — starting with the ecosystem fundamentals, moving through AWS spot instance setup and cost control, and finishing with auto-scaling, security, and a head-to-head comparison with commercial platforms. Each article stands alone; read in order to build the full stack.
Updated October 2026: This article has been corrected: WebODM is a separate project from OpenDroneMap and runs its own engine, ODX. An earlier version gave unsourced GPU speedup figures, listed AMD-based g4ad instances as NVIDIA GPUs, said GPU support had to be compiled, and said interrupted jobs can never resume; those claims, along with several cost and CloudWatch errors, are fixed.
Pricing note: AWS pricing, spot instance rates, and third-party software costs change frequently. Spot prices here are us-east-2 Linux rates from AWS’s spot pricing data on October 23, 2026, and they fluctuate; on-demand prices are AWS’s us-east-2 list prices. Verify all figures against current pricing pages before making infrastructure decisions.
You launched your first EC2 instance. Picked something in the middle. It works. But is it the right size? Maybe you’re paying for a beast when a lightweight would do. Or maybe you’re choking a heavy dataset on underpowered hardware.
Most guides say CPU matters for photogrammetry. They’re wrong. RAM is the constraint. CPU mostly decides how fast a job runs: in the 2,500-image run below, going from 8 to 32 vCPUs cut the time by about a fifth. Memory? That’s the difference between finishing and crashing.
Here’s the real math.
The Binding Constraint: Memory, Not CPU
ODX (the engine behind WebODM, forked from OpenDroneMap’s ODM) has three memory-hungry stages:
-
Feature detection and matching. Extracts SIFT keypoints from every image, then matches them across overlapping images. Thousands of images times thousands of keypoints each — that’s gigabytes right there.
-
Bundle adjustment. Solves camera position and orientation for every image simultaneously. Linear algebra on a massive matrix, and RAM scales with image count faster than you’d expect.
-
Dense point cloud generation. Creates millions of 3D points from matched pixels. Could be 5 million points or 50 million, depending on image count and overlap.
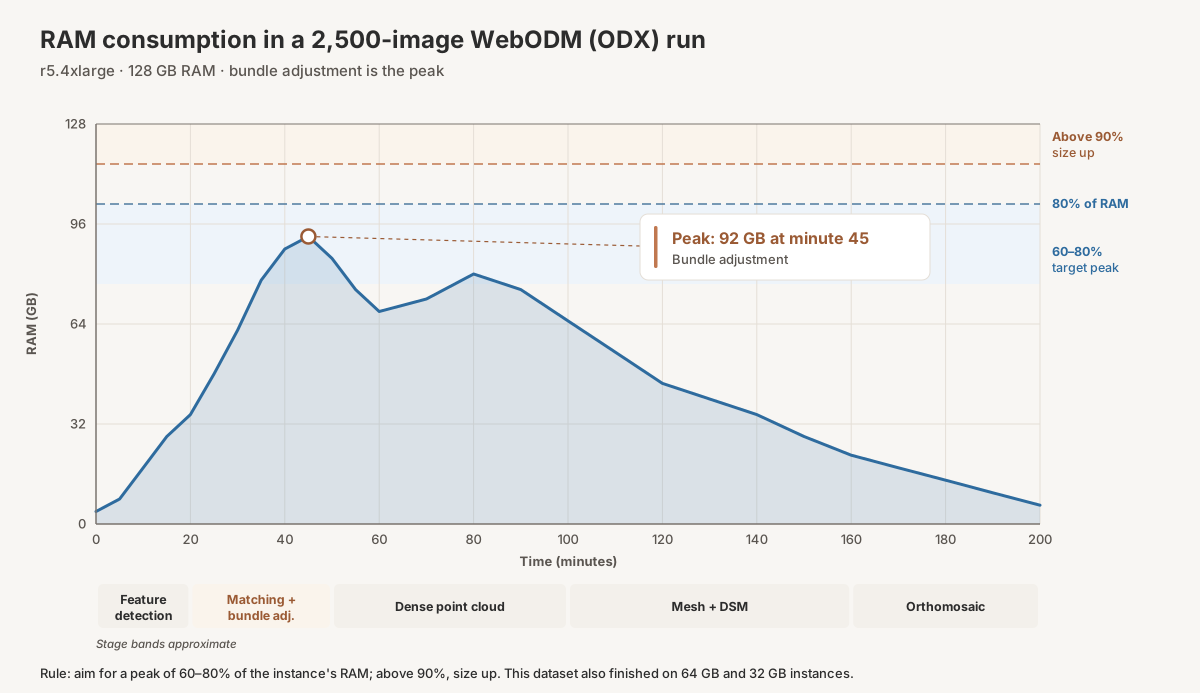
Step 2 is often the killer. Bundle adjustment’s memory grows with the number of images and matched points, so on large datasets it’s where memory tends to peak (it’s the peak in the chart below).
CPU cores speed up feature detection and point cloud generation. Bundle adjustment uses multiple threads too, but it doesn’t scale linearly with core count, so extra cores give diminishing returns there.
One 2,500-image run (software version, image size and quality settings weren’t recorded):
| Instance type | RAM | vCPUs | Processing time |
|---|---|---|---|
| m5.xlarge | 16 GB | 4 | Failed (OOM) |
| m5.2xlarge | 32 GB | 8 | 4 hours |
| r5.2xlarge | 64 GB | 8 | 3.8 hours |
| r5.4xlarge | 128 GB | 16 | 3.2 hours |
| r5.8xlarge | 256 GB | 32 | 3.1 hours |
Look at that table. Adding 8 vCPUs (from r5.2xlarge to r5.4xlarge) shaved about 16 percent off the time. Going from m5.xlarge (16 GB) to m5.2xlarge (32 GB) turned a crash into a completed job. That’s the real win.
Size for memory first, optimize CPU second.
ClusterODX Sizing Table: Image Count to Instance Type
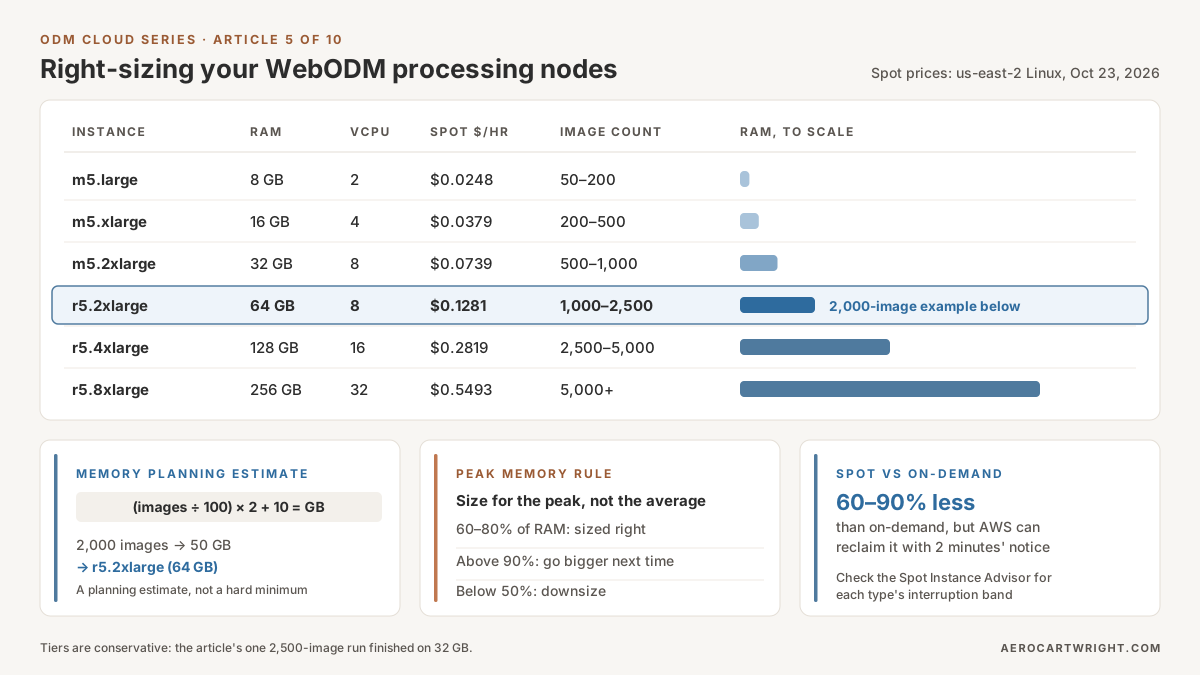
If you’re running ClusterODX (WebODM’s fork of ClusterODM, with optional cloud autoscaling), its imageSizeMapping setting maps image counts to instance types. Here’s the breakdown we use:
| Image count | Recommended instance | RAM | vCPUs | Spot price/hr (us-east-2, Oct 23, 2026) |
|---|---|---|---|---|
| 50–200 | m5.large | 8 GB | 2 | $0.0248 |
| 200–500 | m5.xlarge | 16 GB | 4 | $0.0379 |
| 500–1,000 | m5.2xlarge | 32 GB | 8 | $0.0739 |
| 1,000–2,500 | r5.2xlarge | 64 GB | 8 | $0.1281 |
| 2,500–5,000 | r5.4xlarge | 128 GB | 16 | $0.2819 |
| 5,000–10,000 | r5.8xlarge | 256 GB | 32 | $0.5493 |
| 10,000+ | r5.8xlarge | 256 GB | 32 | $0.5493 |
These tiers are conservative recommendations, not hard minimums. Our 2,500-image run finished on 32 GB, so the 64 GB tier leaves headroom. WebODM’s installation docs are more conservative still: they list 32 GB of RAM (or RAM plus swap) for 500 images, 64 GB for 1,500, 128 GB for 2,500 and 256 GB for 5,000. A run with less RAM than that can still finish, by using swap and running its memory-heavy stages more slowly, as long as peak memory never exceeds RAM plus swap. If you have 1,500 images:
- Smaller (m5.2xlarge, 32 GB): Can finish (our 2,500-image run did), but with less headroom. Datasets with high overlap or high-resolution images may push it into swap or out of memory.
- Recommended (r5.2xlarge, 64 GB): Matches WebODM’s docs for 1,500 images. Took 3.8 hours in our one 2,500-image run.
- Oversized (r5.4xlarge, 128 GB): Took 3.2 hours in that run. Roughly 15 percent faster, but double the cost. Not worth it.
Rule: Pick the smallest instance where peak memory stays around 60–80 percent of its RAM, and never above 90 percent. You need headroom for OS overhead and WebODM buffers.
How to Estimate Your Needed Memory
Quick formula:
Memory needed (GB) = (image_count / 100) × 2 + 10
This gives a planning estimate that sits between our run (2,500 images finished on 32 GB; the formula says 60 GB) and WebODM’s docs table (128 GB for 2,500):
- 500 images: (5 × 2) + 10 = 20 GB → use 32 GB instance (m5.2xlarge)
- 2,000 images: (20 × 2) + 10 = 50 GB → use 64 GB instance (r5.2xlarge)
- 5,000 images: (50 × 2) + 10 = 110 GB → use 128 GB instance (r5.4xlarge)
Process one small test dataset on your chosen instance. Watch memory usage in CloudWatch. If peak stays at 60–80 percent of the instance’s RAM, you’re sized right. Above 90 percent, pick a larger instance next time. Below 50 percent, you can downsize.
AWS Spot vs On-Demand for WebODM Cloud Processing
Spot instances cost 60-90 percent less than on-demand. The catch: AWS can pull the rug with 2 minutes notice. For photogrammetry, that means 4 hours of processing gone and a full restart.
When to Use Spot
Jobs under 6 hours, or jobs you can afford to retry:
Budget 3–4 hours for 1,000 images on r5.2xlarge, a rough planning figure. AWS doesn’t publish a per-job interruption probability. Its Spot Instance Advisor puts each instance type into an interruption-frequency band for the past month: under 5, 5–10, 10–15, 15–20 or over 20 percent. On October 23, 2026 it listed r5.2xlarge in us-east-2 at 10–15 percent; check it for your type and region. A short job is exposed for less time, so if one of your runs gets interrupted, you rerun it. Cost savings outweigh the occasional retry.
Spot pricing for a 3-hour job:
- Spot instance (r5.2xlarge): 3 hours × $0.1281 = $0.38
- On-demand (r5.2xlarge): 3 hours × $0.504 = $1.51
- Savings: $1.13 per job
Process 10 jobs per month, that’s about $11.30 saved. Not huge, but real.
When to Avoid Spot
Jobs over 12 hours, or jobs that can’t be retried:
A 5,000-image dataset on r5.4xlarge may take 8–12 hours, a rough planning range. The longer the job, the more of that month’s interruption risk it’s exposed to, and the Spot Instance Advisor’s band for your instance type is the best guide you’ll get. If it’s interrupted at hour 11, you start over. That’s expensive in time and money.
On-demand for a 10-hour job:
- On-demand (r5.4xlarge): 10 hours × $1.008 = $10.08
- Spot (r5.4xlarge): 10 hours × $0.2819 = $2.82
You’d save $7.26 if uninterrupted. But if interrupted at hour 9, you’ve spent $2.54, then restart and spend another $2.82, total $5.36 — still cheaper than on-demand, but the margin shrinks with every interruption, and repeated retries on a flaky spot pool can erase the savings entirely.
For long jobs: on-demand. A Spot Fleet doesn’t rescue a single long job. It replaces an interrupted instance, but the job that was running on it still starts over.
Mixed Strategy: Capacity-Optimized Spot Fleets
A Spot Fleet is for a pool of NodeODX nodes you launch and attach yourself, to WebODM or ClusterODX, when you run many jobs. ClusterODX’s autoscaler doesn’t use Spot Fleet: it launches one docker-machine instance per task. With capacity-optimized allocation, AWS spreads your instances across instance types and availability zones. If one gets interrupted, the others keep working on their own jobs, and the fleet launches a replacement. Each fleet instance has to start NodeODX at boot (for example from user data) and be added to WebODM or ClusterODX as a node.
Configuration example:
# Launch 4 r5 instances with capacity-optimized allocation
aws ec2 request-spot-fleet --spot-fleet-request-config '{
  "IamFleetRole": "arn:aws:iam::ACCOUNT:role/fleet-role",
  "TargetCapacity": 4,
  "Type": "maintain",
  "AllocationStrategy": "capacityOptimized",
  "SpotPrice": "0.40",
  "LaunchSpecifications": [
    {
      "ImageId": "ami-REPLACE_WITH_REGION_AMI",
      "InstanceType": "r5.2xlarge",
      "KeyName": "your-key",
      "SpotPrice": "0.40"
    },
    {
      "ImageId": "ami-REPLACE_WITH_REGION_AMI",
      "InstanceType": "r5.4xlarge",
      "KeyName": "your-key",
      "SpotPrice": "0.40"
    }
  ]
}'
AMI IDs are region-specific: replace the placeholder with an AMI from your own region. If one r5.2xlarge gets interrupted, fleet launches another. The job that was running on it still has to be resubmitted, but the fleet keeps capacity available for it.
GPU Acceleration: Hype vs. Reality
ODX supports NVIDIA GPUs through CUDA. Its README says the GPU is used “to speed up certain computations.” ODX uses the GPU for feature matching (on datasets of 32 or more images, per modules/osfm.py) and for OpenMVS densification (stages/openmvs.py). Does it help? It can. How much? Nobody publishes a number. Neither the ODX docs nor webodm.org publish a speedup figure, so any speedup percentage you read (including the ones an earlier version of this article printed) is a guess until you benchmark your own data.
What you can calculate is the breakeven. A GPU instance costs more per hour than a CPU instance with the same RAM, so it only saves money if it finishes enough faster to cover the gap:
- r5.2xlarge (64 GiB, CPU only): $0.504/hour on-demand in us-east-2. A 4-hour job costs 4 × $0.504 = $2.02.
- g6.4xlarge (64 GiB, one NVIDIA L4): $1.3232/hour on-demand in us-east-2 (AWS price list published September 25, 2026). To match $2.02, the same job has to finish in $2.02 ÷ $1.3232 = about 1.5 hours, roughly 2.6 times faster than the CPU run.
That’s a hypothetical comparison, not a measurement. Whether ODX gets anywhere near that on your datasets is exactly what you need to test.
When GPU might make sense:
- Hard SLA deadlines — you need to finish by a certain time, period, and a shorter run is worth paying for
- High job volume, where your own benchmark shows the GPU instance beating the breakeven above
For typical drone mapping (500-2,000 images), start with CPU. It’s usually cheaper, and it’s simpler to run.
If you do want GPU:
Pick an instance with an NVIDIA GPU: g4dn (T4), g5 (A10G), g6 (L4) or g6e (L40S). Don’t pick g4ad: those instances use AMD Radeon Pro V520 GPUs, and ODX’s GPU support is CUDA-based, so it won’t use them. Then run one job with GPU and one without on the same dataset, measure the time savings, and calculate your breakeven.
The —max-concurrency Flag and When It Helps
ODX has a --max-concurrency option that caps how many processes it runs at once. Default is one per CPU core. In WebODM you set it per task as the max-concurrency processing option. On a NodeODX node you can also cap it for every task with NodeODX’s own --max_concurrency flag:
# Run a NodeODX node that caps every task at 8 processes
docker run -p 3000:3000 webodm/nodeodx --max_concurrency 8
Why would you limit cores? Two reasons.
First, memory savings. ODX’s own help text says peak memory is “~1GB per thread and 2 megapixel image resolution,” so fewer parallel processes means a lower peak. On a 32-core machine, setting --max-concurrency 8 keeps only 8 processes running at once in the parallel stages. You trade time for memory headroom.
Second, on-prem power optimization. If your job only needs 16 cores worth of parallelism, capping it there saves power. On AWS this doesn’t matter (you pay for the full instance regardless), but on your own hardware it can.
Default: Use all cores. Change only if you’re hitting memory limits.
Example: 2,500-image dataset on r5.4xlarge (128 GB, 16 vCPUs) is hitting 95 percent memory. Set --max-concurrency 8. Processing takes 3.5 hours instead of 3.2 hours (about 9 percent slower), but memory drops to 85 percent. Stable, no crashes.
Real Cost Calculations: Three Scenarios
Scenario 1: Small Operator, 200 Images/Month
- 1 job per month, 200–500 images typical
- Workflow: Upload to S3, process once, download, delete
- Instance choice: m5.xlarge (16 GB, ~$0.04/hr spot)
Monthly cost:
- Processing: 1 job × 2 hours × $0.0379 = $0.08
- Storage (S3): 10 GB × $0.023 = $0.23
- Data transfer: 40 GB download, inside AWS’s free allowance = $0
- Monthly total: $0.31
- Annual: $3.72
The first 100 GB a month of data transfer out to the internet is free, so if this is your only egress, the transfer charge is $0. Without that allowance, the 40 GB would cost 40 × $0.09 = $3.60, for a monthly total of $3.91 and $46.92 a year. Presigned URLs don’t change this: the bucket owner pays egress whether the client downloads through a presigned URL or not.
Scenario 2: Mid-Size Operator, 10 Jobs/Month
- 10 jobs per month, 1,000 images per job
- Workflow: Regular processing, client delivery, archive outputs
- Instance choice: r5.2xlarge (64 GB, ~$0.13/hr spot)
Monthly cost:
- Processing: 10 jobs × 3.5 hours × $0.1281 = $4.48
- Storage (S3, with lifecycle policy): 600 GB mixed tiers = $7.50
- Data transfer: client downloads via presigned URLs are still billed as egress ($0.09/GB after the first 100 GB a month); not included here
- Monthly total (before egress): $11.98
- Annual (before egress): $143.76
Optimization: Switch 5 of 10 jobs to on-demand ($0.504/hr) instead of spot, reducing interruption risk. Processing becomes 5 × 3.5 × $0.504 = $8.82 on-demand plus 5 × 3.5 × $0.1281 = $2.24 spot, so the total rises to ~$18.56/month, ~$223/year. Insurance against reruns.
Scenario 3: Large Shop, 50 Jobs/Month, Parallel Processing
- 50 jobs per month across multiple image counts
- Workflow: ClusterODX auto-scaling, 4 instances concurrent
- Mixed instance types: m5.2xlarge (20 jobs), r5.2xlarge (20 jobs), r5.4xlarge (10 jobs)
Monthly cost:
- Processing (ClusterODX autoscaled spot nodes):
- 20 jobs × m5.2xlarge × 2 hrs × $0.0739 = $2.96
- 20 jobs × r5.2xlarge × 3.5 hrs × $0.1281 = $8.97
- 10 jobs × r5.4xlarge × 6 hrs × $0.2819 = $16.91
- Subtotal: $28.84
- Storage (S3, heavy archival): 2,500 GB = $25–30
- Data transfer: billed as egress after the first 100 GB a month; not included here
- Monthly total (before egress): $54–59
- Annual (before egress): $646–706
At this scale, spot pricing and ClusterODX’s per-job nodes keep compute and storage under $1.20 per job ($58.84 ÷ 50 = $1.18 at the high end). A year of processing for a small team: about $650–710, plus whatever your clients’ downloads cost in egress.
Instance Type Comparison: Full Reference Table
For quick lookups. Spot prices are us-east-2 Linux on October 23, 2026, and they fluctuate. Image ranges match the ClusterODX tiers above:
| Instance | RAM | vCPUs | On-demand $/hr | Spot $/hr | Good for |
|---|---|---|---|---|---|
| m5.large | 8 GB | 2 | $0.096 | $0.0248 | up to 200 images |
| m5.xlarge | 16 GB | 4 | $0.192 | $0.0379 | 200–500 images |
| m5.2xlarge | 32 GB | 8 | $0.384 | $0.0739 | 500–1,000 images |
| m5.4xlarge | 64 GB | 16 | $0.768 | $0.1507 | 1,000–2,500 images |
| r5.xlarge | 32 GB | 4 | $0.252 | $0.0606 | 500–1,000 images |
| r5.2xlarge | 64 GB | 8 | $0.504 | $0.1281 | 1,000–2,500 images |
| r5.4xlarge | 128 GB | 16 | $1.008 | $0.2819 | 2,500–5,000 images |
| r5.8xlarge | 256 GB | 32 | $2.016 | $0.5493 | 5,000–10,000+ images |
Memory-optimized instances (r5, r6) cost more but handle larger datasets. General-purpose (m5, m6) are cheap but hit limits faster.
Monitoring Instance Performance
Picked an instance? Run a job and verify it’s actually the right fit.
CloudWatch Memory Metrics
EC2 doesn’t report memory to CloudWatch on its own. Its default metrics cover CPU, disk and network only. Install the CloudWatch agent on the instance and have it collect mem_used_percent, with the instance ID added as a dimension. The agent publishes to the CWAgent namespace:
# Peak memory use during the run (requires the CloudWatch agent)
aws cloudwatch get-metric-statistics \
  --namespace CWAgent \
  --metric-name mem_used_percent \
  --dimensions Name=InstanceId,Value=i-1234567890abcdef0 \
  --start-time 2026-05-20T00:00:00Z \
  --end-time 2026-05-20T04:00:00Z \
  --period 300 \
  --statistics Maximum
What the numbers tell you:
- Peak above 90 percent: Too small. Go bigger next time.
- Peak 60-80 percent: Right where you want to be.
- Peak below 50 percent: You’re overpaying. Downsize.
Processing Time Benchmarking
Process one known dataset (say, 1,000 images) on your chosen instance. Write down total time, peak memory, and CPU utilization. Next time you run a similar image count, you’ll know immediately whether you’re sized right.
FAQ
Q: Can I change instance size mid-processing?
No. Stop the processing, terminate the instance, relaunch with a bigger one, restart the job.
Q: Will a bigger instance process faster?
Only if memory-bound. Upgrade r5.2xlarge (64GB, 8 vCPUs) to r5.4xlarge (128GB, 16 vCPUs): 10–20 percent faster. Upgrade to r5.8xlarge (256GB, 32 vCPUs): maybe 20 percent faster. Gains flatten because some stages, bundle adjustment among them, don’t scale linearly with core count.
Q: Should I use on-demand or spot?
For jobs under 6 hours: spot. For jobs 6–12 hours: mix (some on-demand, some spot). For jobs over 12 hours: on-demand. If budget is tight and reruns are acceptable: always spot.
Q: What if my job gets interrupted mid-processing?
It depends on whether the task’s files survive. ODX saves each stage’s results in the task folder and can restart from a chosen stage (--rerun-from, or Restart in WebODM’s task menu). If the instance stops but its EBS volume survives, you can pick up from the last finished stage instead of starting over. If AWS terminates a spot instance and its volume goes with it, the run is lost and you restart from the beginning. ClusterODX doesn’t move a running task to a new node either: its autoscaler launches nodes for new tasks, so you resubmit the job.
Q: Do I need to configure anything for GPU if I choose a GPU instance?
Yes, but there’s no compiling. Use an instance with an NVIDIA GPU (not AMD-based g4ad), install the NVIDIA driver and the NVIDIA Container Toolkit on Linux, then start WebODM with ./webodm.sh start --gpu, which uses the webodm/nodeodx:gpu image. To run ODX on its own, use the prebuilt webodm/odx:gpu image with --gpus all. The Windows build has GPU support enabled by default.
Q: Can I process multiple datasets in parallel on one instance?
Yes, but they share the instance’s RAM. NodeODX sets how many tasks run at once with its -q / --parallel_queue_processing option, and extra tasks wait in its queue. On a node sized for one big job, run one task at a time. If you want parallel processing of large datasets, launch multiple instances (ClusterODX’s autoscaler gives each task its own node).
Bottom Line
Size for memory, not CPU. Too little RAM is what fails a job outright: our 2,500-image run crashed on 16 GB, finished on 32 GB, and ran a little faster on 64 GB. WebODM’s conservative docs table asks for 128 GB of RAM (or RAM plus swap) at that size. CPU barely matters beyond 8 cores for datasets under 5,000 images.
Use the ClusterODX table above. For 1,000 images: r5.2xlarge (64 GB, ~$0.13/hr spot). For 5,000: r5.4xlarge (128 GB, ~$0.28/hr spot). Spot for jobs under 6 hours. On-demand for longer runs.
Start with CPU. For most drone mapping, CPU-only is usually cheaper. If turnaround matters, benchmark a GPU instance against the breakeven above before you commit.
After your first run, check peak memory as a share of the instance’s RAM. Below 50 percent? Downsize. Above 90 percent? Go bigger.
For next steps, see Walk 6: Sharing Results — From WebODM to Client Map Link for delivering outputs efficiently.